

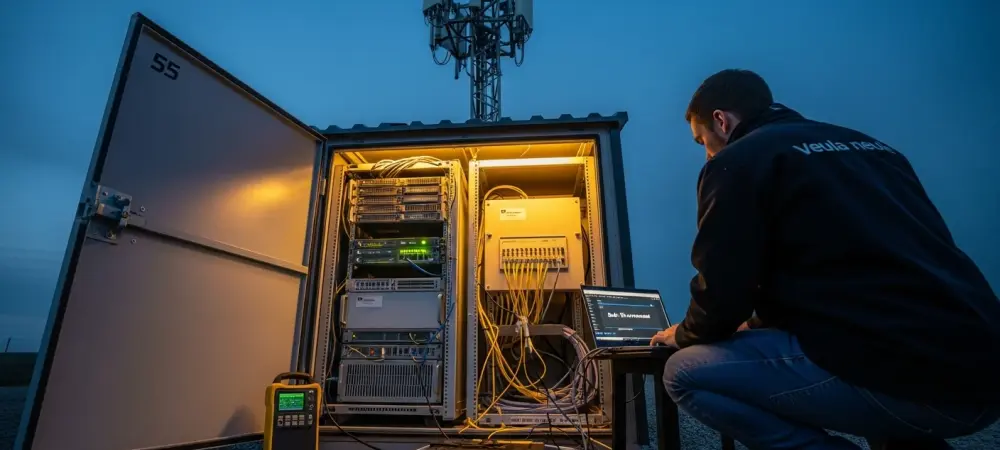
Pressure to keep data sovereign, deliver sub-10-millisecond response times, and harden operational resilience met a breaking point as AI pilots turned into production systems that could not live only in distant public regions. Enterprises now need the same cloud services and controls to run in plants, branches, clinics, and sovereign facilities as in hyperscale zones, and they need that consistency without sacrificing security or speed. Kyndryl’s expanded alignment with Google Cloud directly addressed that reality by extending cloud-native operations into customer-controlled sites through Google Distributed Cloud, modernizing on Google Kubernetes Engine, and adding a services layer to govern it all. The result promised a single operating model across hybrid, multicloud, on-premises, and edge, with workload placement dictated by law, latency, and cost rather than platform gaps. For AI-heavy workloads, that meant training and inference close to data, while still tapping a unified toolchain.
Why It Matters
Market Drivers
Regulatory frameworks tightened across regions, and the effect landed squarely on data. Banks facing ring-fencing rules, hospitals governed by HIPAA-equivalent mandates abroad, and public-sector agencies bound by national residency requirements needed precise control over where data sits, who can access it, and how it moves. At the same time, industrial sites poured out telemetry from sensors, cameras, and PLCs that could not tolerate round trips to distant regions for every inference. Retailers demanded in-store personalization that updates in seconds, not minutes. Telecom operators needed RAN-adjacent processing to keep user plane traffic snappy. These are not edge curiosities; they are operational baselines. The shift to a distributed model grew from these converging pressures, where centralized public cloud alone struggled to meet compliance, performance, and resilience goals simultaneously.
Moreover, AI maturity transformed the risk profile. Early proofs of concept could anonymize small samples in a lab; production systems must handle full-fidelity data, explainability obligations, and supply chain constraints for hardware accelerators. Moving training and inference across borders triggered questions about lawful bases for transfer and vendor lock-in if models or features were tied to a single region. Observability fractured as teams stitched together multiple tools across colocation, private data centers, and clouds, often yielding blind spots in identity or secrets management. The need became clear: consolidate governance and visibility while allowing workload mobility. That demanded uniform policy, identity, and logging, backed by a platform that speaks Kubernetes everywhere but respects the physical realities of factories, branches, and sovereign facilities.
Value Proposition
The Kyndryl–Google Cloud proposition centered on choice without chaos. With Google Distributed Cloud extending services into customer facilities and GKE providing a consistent Kubernetes substrate, organizations could standardize on the same APIs, controllers, and security policies across sites. That enabled developers to target a single platform for CI/CD, templates, and service meshes, while operators enforced identity, secrets rotation, and network segmentation once and applied them everywhere. If a payments microservice needed to run in a cardholder data environment to satisfy PCI-DSS while latency-sensitive fraud models lived next to point-of-sale endpoints, the controls remained uniform. When regulations shifted or seasonal peaks demanded capacity swings, teams could relocate containers between on-prem clusters and nearby public regions without rewriting application logic or redefining governance.
This coherence also reduced tool sprawl. Rather than separate pipelines, monitoring stacks, and runtime policies per location, teams consolidated around a unified control plane. Policy-as-code traveled with workloads, audit trails remained intact, and drift detection prevented configuration entropy across hundreds of clusters. Data services followed suit: consistent encryption, key management, and data classification tightened security posture while preserving portability. In practice, that meant a healthcare system could run inference against imaging data on-site using GPUs integrated with Google Distributed Cloud, backpropagate insights to a regional model registry, and sync non-sensitive metadata to a multiregion analytics lake for system-wide reporting. The business outcome was agility under constraint: place workloads where they must run, not merely where they can.
What’s in the Offering
Architecture and Capabilities
At the core sits Google Distributed Cloud, which brings managed control planes, Kubernetes, and select Google Cloud services into customer environments, from data centers to far-edge locations. On top, Google Kubernetes Engine offers the familiar orchestration layer for containerized applications with autoscaling, rolling updates, and native policy controllers. A unified control plane aligned policy, IAM, and observability across private, on-prem, edge, and public regions, allowing teams to enforce Gatekeeper constraints, apply service mesh policies, and monitor golden signals through consistent telemetry. Data locality was not an afterthought; storage and processing resided precisely where statutes or strategy required, with data egress tightly governed. For AI, proximity to data cut inference latency and trimmed backhaul costs, while still allowing access to centralized MLOps registries and pipelines.
Building on this foundation, modernization became intentional. Legacy apps moved through stages—containerization, refactoring, or full re-architecture—guided by patterns proven on GKE. Stateful services used operators and StatefulSets to preserve reliability, while event-driven components adopted Pub/Sub-compatible tooling where available. Security wrapped every layer: Binary Authorization, workload identity, secrets managers, and policy enforcement points created a defensible runtime. Tooling such as Gemini Enterprise assisted with code analysis, YAML hygiene, and dependency mapping to speed modernization and reduce toil. Network design mattered as much as compute: private service connects, hierarchical firewalls, and consistent ingress controllers helped standardize east–west and north–south traffic. The outcome aligned with platform engineering goals—repeatable environments, paved roads for developers, and fewer bespoke exceptions.
Services and Use Cases
Kyndryl layered advisory, implementation, and managed services around the stack to bridge skills gaps and accelerate outcomes. Engagements typically began with an estate assessment, mapping apps to placement policies based on sovereignty, latency, and data sensitivity. Architects then designed target landing zones: edge clusters for real-time inference, on-prem clusters for regulated datasets, and regional GKE for burstable or global services. Implementation covered cluster build-out, CI/CD pipelines with GitOps, policy codification, and observability integration. Managed services handled day-two operations: patching, capacity planning, incident response, cost guardrails, and continuous compliance. This orchestration mattered because enterprises rarely succeed with tooling alone; operational discipline, shared taxonomies, and decision matrices for workload mobility turned the strategy into a predictable practice.
Concrete use cases illustrated the fit. A manufacturer streamed machine-vision data from cameras to a plant-adjacent Google Distributed Cloud cluster for sub-20-millisecond defect detection, synchronized model versions with a central registry, and pushed anonymized metrics to a regional analytics layer. A global bank ran sanctions screening microservices in sovereign facilities while keeping analytics in nearby regions, using consistent IAM and audit logs across all sites. A healthcare network conducted inference on radiology images on-prem to meet residency rules, then retrained foundation models during off-hours in a regional GKE cluster where data-sharing agreements allowed. For next steps, platform teams should establish placement policies tied to data classifications, adopt GitOps for immutable environments, and define an exit path for any workload—including AI pipelines—so migration, rotation, and rollback remained straightforward. Taken together, these moves positioned organizations to scale AI safely and efficiently under real-world constraints.