

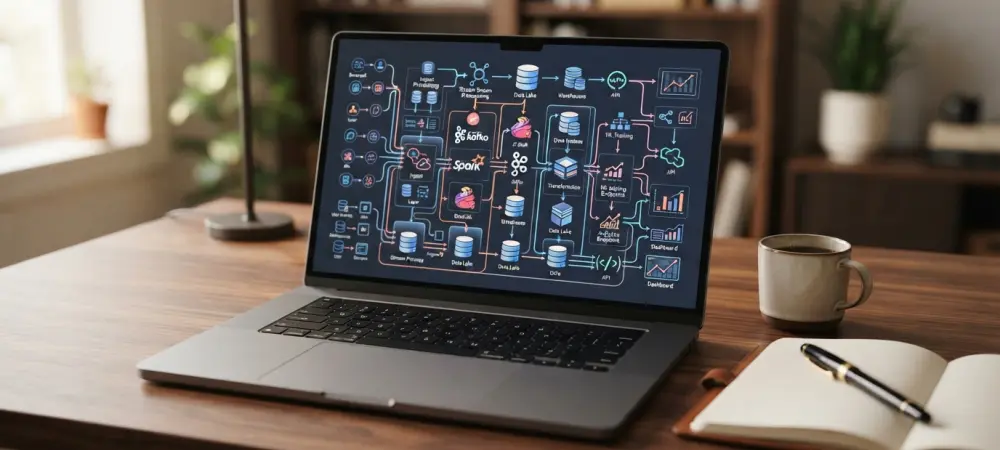
Anthropic’s native OpenTelemetry support eliminates the need for separate silos of debugging output by centralizing traces in Unity Catalog. This shift represents a significant milestone for developers who have long struggled with the fragmented nature of agentic workflows where logs and performance metrics often vanish into disparate proprietary dashboards. As large language models transition from simple chat interfaces to complex, multi-step agents capable of independent reasoning and tool execution, the demand for transparent execution paths has reached a fever pitch. By establishing a direct pipeline between the Claude platform and Databricks MLflow, engineering teams can now observe every internal thought process and external API call in real-time. This level of granular visibility ensures that when an agent hallucination occurs or a tool call fails, the root cause is immediately accessible within a unified data estate. The integration effectively bridges the gap between raw model output and structured enterprise governance, allowing for a more disciplined approach to AI lifecycle management during the 2026 to 2028 development cycle.
1. Unified Instrumentation Across Development Surfaces
The architecture of this integration covers three distinct build surfaces simultaneously, ensuring that regardless of how a developer interacts with Claude, the telemetry remains consistent. The Anthropic SDKs, the Messages API, and Managed Agents are all natively equipped to handle OpenTelemetry exports, while Claude Code and the Claude Agent SDK join the ecosystem through simple environment configuration. This comprehensive coverage means that experimental prototypes and production-grade agents share the same monitoring framework, reducing the friction typically associated with scaling AI applications. Developers no longer need to write custom logging wrappers or manually instrument every tool call to understand what is happening under the hood. Instead, the system automatically captures spans that record model requests, timing data, and the precise sequence of tool interactions. This standardized approach allows teams to maintain a clear audit trail of agent behavior without sacrificing the speed of iteration or introducing unnecessary code complexity.
At the technical core of this collaboration is the use of the OpenTelemetry Protocol (OTLP), an industry standard that facilitates the collection and export of service signals across diverse environments. Claude’s native instrumentation transmits these signals via the OTLP http/protobuf protocol to the Databricks Zerobus Ingest service. This specialized ingestion layer is designed to handle high queries per second (QPS) with minimal latency, ensuring that the performance of the agent itself is not degraded by the overhead of telemetry collection. Once received, these traces are stored directly in Unity Catalog tables that are linked to specific MLflow experiments. This allows engineers to query trace data using standard SQL, making it possible to integrate AI performance metrics into existing business intelligence dashboards. The marriage of OTEL flexibility with the robust ingestion capabilities of Zerobus creates a resilient backbone for monitoring complex agentic loops that might involve dozens of recursive steps or parallel tool executions.
2. Governance and Detailed Investigation Capabilities
Placing Claude traces within the Unity Catalog framework provides a layer of enterprise governance that was previously difficult to achieve in agentic development. Unity Catalog governs access to the sensitive data contained within agentic traces, which often include proprietary tool inputs, customer information, and internal system metadata. By leveraging existing identity and access management policies, organizations can ensure that only authorized personnel can inspect the inner workings of their AI agents. This is particularly critical when dealing with content mode settings, where inputs and outputs are recorded in full for deep debugging purposes. Since the governance travels with the data, the security posture of the organization remains intact even as telemetry is shared across different teams for evaluation or auditing. Furthermore, the ability to store these traces in a centralized, governed repository simplifies compliance reporting, as every model decision and tool interaction is documented and protected within the organization’s environment.
Beyond simple logging, the integration addresses the black box problem where an agent provides a plausible but ultimately incorrect answer. Anthropic’s documentation highlights that an agent might miss a crucial finding or repeatedly read the same source without progressing toward a solution. Traces provide the diagnostic depth required to investigate these subtle failures by revealing the model and tool calls occurring behind the scenes. Within the MLflow interface, engineers can examine the execution as individual spans, pinpointing exactly where a reasoning chain deviated or where a tool failed to provide the necessary context. This level of detail is essential for identifying related failure cases and testing whether a prompt adjustment or a logic change actually resolves the underlying issue. By treating every agent interaction as a traceable series of events, teams can move away from anecdotal troubleshooting and toward a data-driven debugging process that treats model behavior as a measurable engineering problem to be solved.
3. Advanced Evaluation and Remediation Loops
The implementation of these tools changed the way engineering teams approached the iterative refinement of their agentic systems. By utilizing MLflow’s analyze trace action, developers leveraged Genie Code to scrutinize recorded executions and identify expensive steps or missing context that hindered performance. This proactive stance allowed for the creation of Review Queues, where domain experts evaluated selected traces to build a repository of gold-standard responses for future training. As the system evolved, organizations successfully deployed LLM judges to provide objective scores on agent behavior, such as detecting redundant tool calls or verifying adherence to specific output formats. This transition from manual oversight to automated, governed evaluation enabled a more robust development cycle that significantly reduced the time between failure detection and production fixes. Ultimately, the integration of Claude’s native tracing into the Databricks ecosystem provided a scalable roadmap for maintaining high-quality AI agents.
To maximize the impact of this integrated tracing system, organizations adopted a strategy of continuous evaluation by scheduling automated scans of trace metadata. This allowed teams to detect recurring issues, such as missing arguments that broke tool integrations, before they impacted a wider user base. After identifying a recurring failure, engineers built and baselined new scorers on recent trace data to ensure that subsequent model updates provided a measurable improvement in reliability. This rigorous approach to performance monitoring transformed the development of AI agents from an experimental art into a precise engineering discipline. Moving forward, the focus shifted toward optimizing token usage and reducing latency by analyzing the timing of individual spans within the MLflow dashboard. By centralizing these insights, businesses ensured that their AI deployments remained cost-effective and responsive, providing a clear competitive advantage in an increasingly agent-centric technological landscape.