

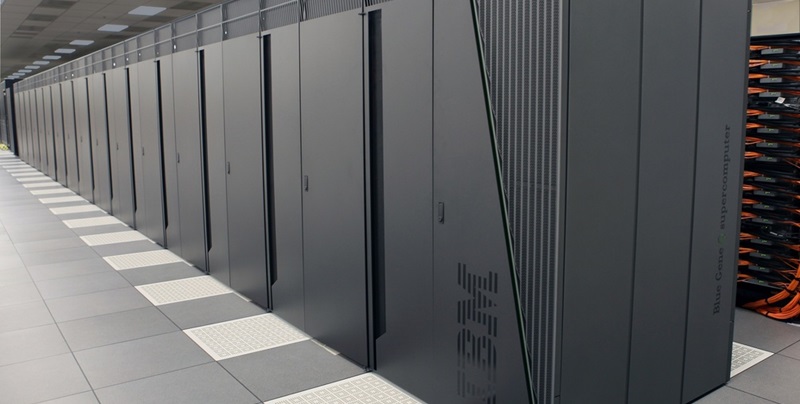
The Frontier supercomputer at ORNL has recently secured its position as the number one supercomputer on the Top500.org list, reaching an impressive performance of 1.194 Exaflop/s using 8,699,904 cores. This significant achievement reflects the success of implementing effective strategies for training large language models (LLMs) and optimizing the model training process.
Strategies for Efficient Training of Large Language Models (LLMs)
The new records achieved by the Frontier supercomputer can be attributed to the implementation of highly efficient methodologies for training LLMs. By applying advanced techniques, the research team behind Frontier optimized the model training process to attain unparalleled results.
Extensive Testing of LLMs
To push the boundaries of LLM training, the team conducted extensive testing with models containing 22 billion, 175 billion, and 1 trillion parameters. These tests provided valuable insights and yielded remarkable results, showcasing the immense potential of the Frontier supercomputer.
Utilization of AMD MI250X AI Accelerators
Surprisingly, the team accomplished these remarkable results by utilizing relatively outdated hardware – the AMD MI250X AI accelerators. By employing up to 3,000 of these accelerators, the researchers demonstrated the incredible performance capabilities of the Frontier supercomputer, even with aging hardware.
The Immense Performance Potential of the GPU Pool
A noteworthy aspect of the Frontier supercomputer is its housing of a staggering 37,000 MI250X GPUs. This highlights the tremendous performance potential when the entire GPU pool is employed for LLMs. The scale of this achievement emphasizes the capacity for future advancements in GPU-accelerated AI research.
Future Improvements with AMD MI300 GPU Accelerators
The success of the Frontier supercomputer sets the stage for further progress as AMD plans to implement its cutting-edge MI300 GPU accelerators in upcoming supercomputers. These next-generation accelerators are expected to significantly enhance AI performance, promising even more remarkable achievements in the field.
GPU Throughputs and Scaling Efficiencies
When discussing the performance of the LLM training process, GPU throughputs are an important metric to consider. The research team achieved impressive throughputs of 38.38%, 36.14%, and 31.96% for the 22 Billion, 175 Billion, and 1 Trillion parameter models, respectively. Additionally, the training of the 175 Billion and 1 Trillion parameter models reached 100% weak scaling efficiency with 1024 and 3072 MI250X GPUs, surpassing expectations. Strong scaling efficiencies of 89% and 87% were also accomplished for the 175 Billion and 1 Trillion parameter models, highlighting the remarkable capabilities of Frontier.
Significance of Generative AI Hardware Advancements
The advancements in hardware designed specifically for generative AI are pivotal in meeting the growing computing power demands in the server and data center segment. The accomplishments of the Frontier supercomputer underscore the importance of continued development in this field, as these advances propel AI research and applications to new levels of performance and efficiency.
The Frontier supercomputer at ORNL has made an indelible mark by achieving groundbreaking performance as the number one supercomputer on the Top500.org list. Its success is the culmination of effective strategies for LLM training, extensive testing, and the intelligent utilization of aging but powerful hardware. As AMD prepares to introduce its MI300 GPU accelerators, the future looks even more promising for the frontier of AI research. This remarkable progress highlights the ongoing evolution of supercomputing and AI technology, ensuring that we are poised to usher in a new era of transformative advancements.