

In an era where artificial intelligence (AI) is reshaping the technological landscape, the roles of data scientists and machine learning engineers have emerged as critical components in the AI workflow. As organizations strive to integrate AI technologies to boost efficiency, profitability, and innovation, understanding how these roles intersect and diverge has become increasingly important. Through this analysis, we explore the distinct yet complementary duties of data scientists and machine learning engineers across various applications and industries.
Introduction to Data Scientists and Machine Learning Engineers
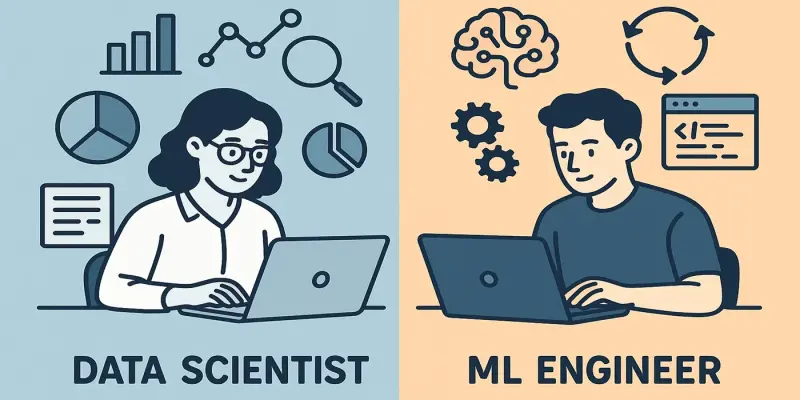
Data scientists and machine learning engineers are at the forefront of technological advancement, each playing specialized roles in the development of AI systems. Data scientists serve as the architects in this realm, focusing on the design and underlying principles of AI solutions by identifying relevant business problems, crafting algorithms, and managing the data analysis process. Meanwhile, machine learning engineers take on the role of builders, tasked with the deployment, optimization, and continuous refinement of machine learning models. This dynamic highlights their shared objective of elevating AI’s capacity to solve complex issues across numerous domains.
The relevance of these roles is underscored by their vital contributions to AI and machine learning industries. Data scientists delve into statistical analysis and data visualization to derive actionable insights, whereas machine learning engineers specialize in model deployment and system engineering. Together, they form a cohesive partnership essential to the successful implementation of AI projects, seamlessly bridging the gap between data theory and practical application.
Core Responsibilities and Roles
Defining the Roles: Design vs. Deployment
Data scientists are charged with exploring and visualizing data while creating sophisticated algorithms and models tailored to specific business challenges. Through a deep understanding of statistical methods and data manipulation, data scientists convert raw data into meaningful insights that inform business strategies and decisions. For example, a data scientist might develop predictive models to forecast consumer behavior, thereby helping companies to optimize their marketing efforts and product offerings. In contrast, machine learning engineers focus on transforming these data-driven insights into tangible, operational systems. They manage the entire lifecycle of machine learning models, which includes coding, testing, and deploying algorithms within production environments. Key responsibilities include automating repetitive tasks, streamlining model workflows, and ensuring robust system performance in real-world applications—like implementing real-time recommendation systems for e-commerce platforms.
Skills and Expertise Required
The skill sets required for data scientists and machine learning engineers, while overlapping in certain areas, diverge in their core competencies. Data scientists require proficiency in statistical analysis, data visualization, and the use of analytics tools, which are crucial for dissecting large data sets and deriving insights. Their expertise often extends to programming languages such as Python and R, and they possess strong communication skills to convey complex analysis to non-expert stakeholders. Machine learning engineers, on the other hand, are anchored in software engineering and programming. They demonstrate adeptness in languages like Python, Java, and C++, as well as machine learning frameworks such as TensorFlow and PyTorch. Their role demands a solid understanding of data structures, algorithms, and software development practices, ensuring the reliability and scalability of deployed models.
Educational Background and Training
The educational paths of data scientists and machine learning engineers denote the emphasis of their respective roles. Data scientists generally hold advanced degrees, such as a master’s or doctorate in fields like mathematics, statistics, or computer science. These programs equip them with a theoretical foundation in data analysis and modeling, vital for executing high-level data strategies. Machine learning engineers, while also benefiting from computer science or related degrees, place a higher emphasis on engineering coursework. Specialized training in machine learning libraries and system architecture is paramount, allowing them to translate theoretical models into functional, enterprise-grade applications. Credentials in software engineering and practical experience through internships or projects are essential for this role.
Challenges and Considerations
The challenges faced by data scientists and machine learning engineers vary in technological and ethical dimensions. Data scientists must grapple with the complexities of translating massive data sets into actionable insights, often confronting issues like data quality, privacy constraints, and ethical data handling. These challenges demand a rigorous approach to data governance and meticulous validation processes to maintain integrity in analysis.
Machine learning engineers face the intricate task of optimizing and scaling AI models for production. Technical difficulties such as model integration, debugging, and ensuring robust performance under various conditions are common hurdles. Additionally, ethical considerations around model biases and their potential societal impact necessitate ongoing vigilance and the implementation of fairness audits in model deployment.
Conclusion and Recommendations
In reviewing the comparative roles of data scientists and machine learning engineers, the nuanced differences in their responsibilities, skills, and training become evident. Data scientists excel in data interpretation and strategy formation, while machine learning engineers focus on bringing these insights to life through deployment and systems optimization. For industries like finance and healthcare, where precise data analysis and model reliability are crucial, employing both roles can synergistically enhance AI initiatives.
As AI continues to evolve, organizations should consider aligning their AI endeavors with the strengths of each profession. Businesses focused on data-driven decision making and insights generation may lean toward data scientists, while those emphasizing model deployment and operational efficiencies might benefit more from engaging machine learning engineers. Recognizing the complementary nature of these roles offers a strategic advantage, driving technological innovation and maintaining a competitive edge in an increasingly data-centric world.